 Sam Davis · Sydney · September 2026
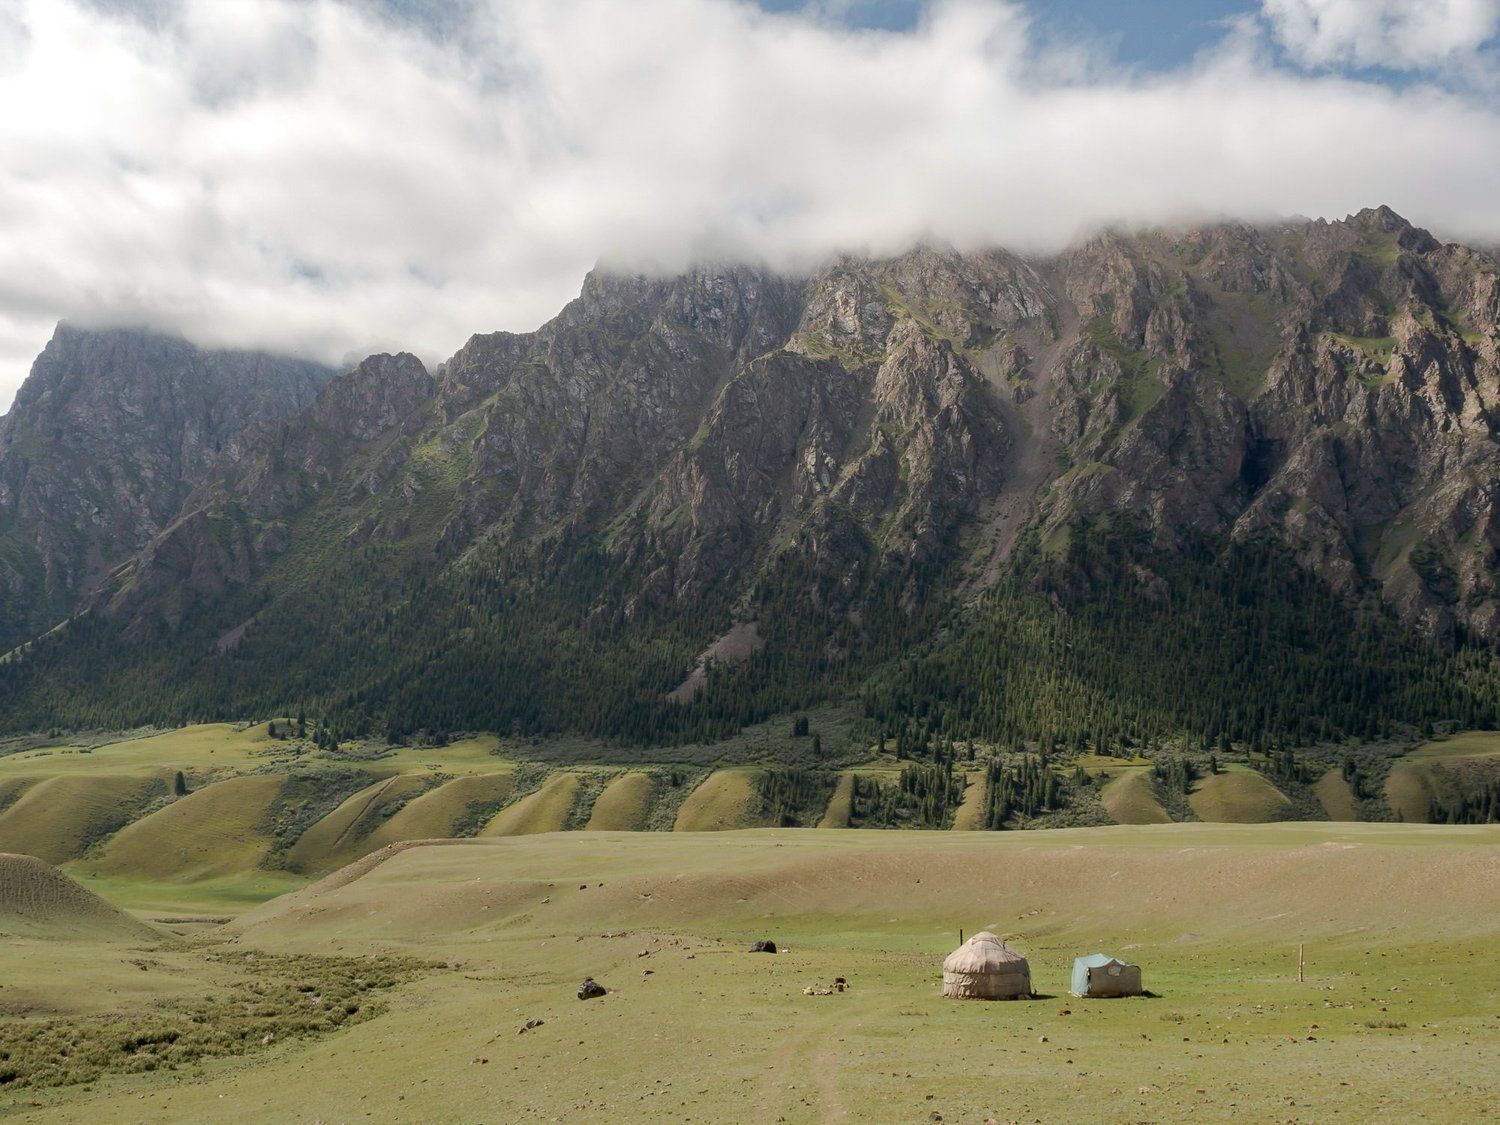
Two men in a valley
In August 2021 I was 24, in the Kuiluu Valley in the Tian Shan mountains of Kyrgyzstan, with four other climbers from the British Alpine Club. The trip had already been delayed a year by COVID. We were there to climb a mountain nobody had climbed before, and we did. We called it Pik Perseverance.
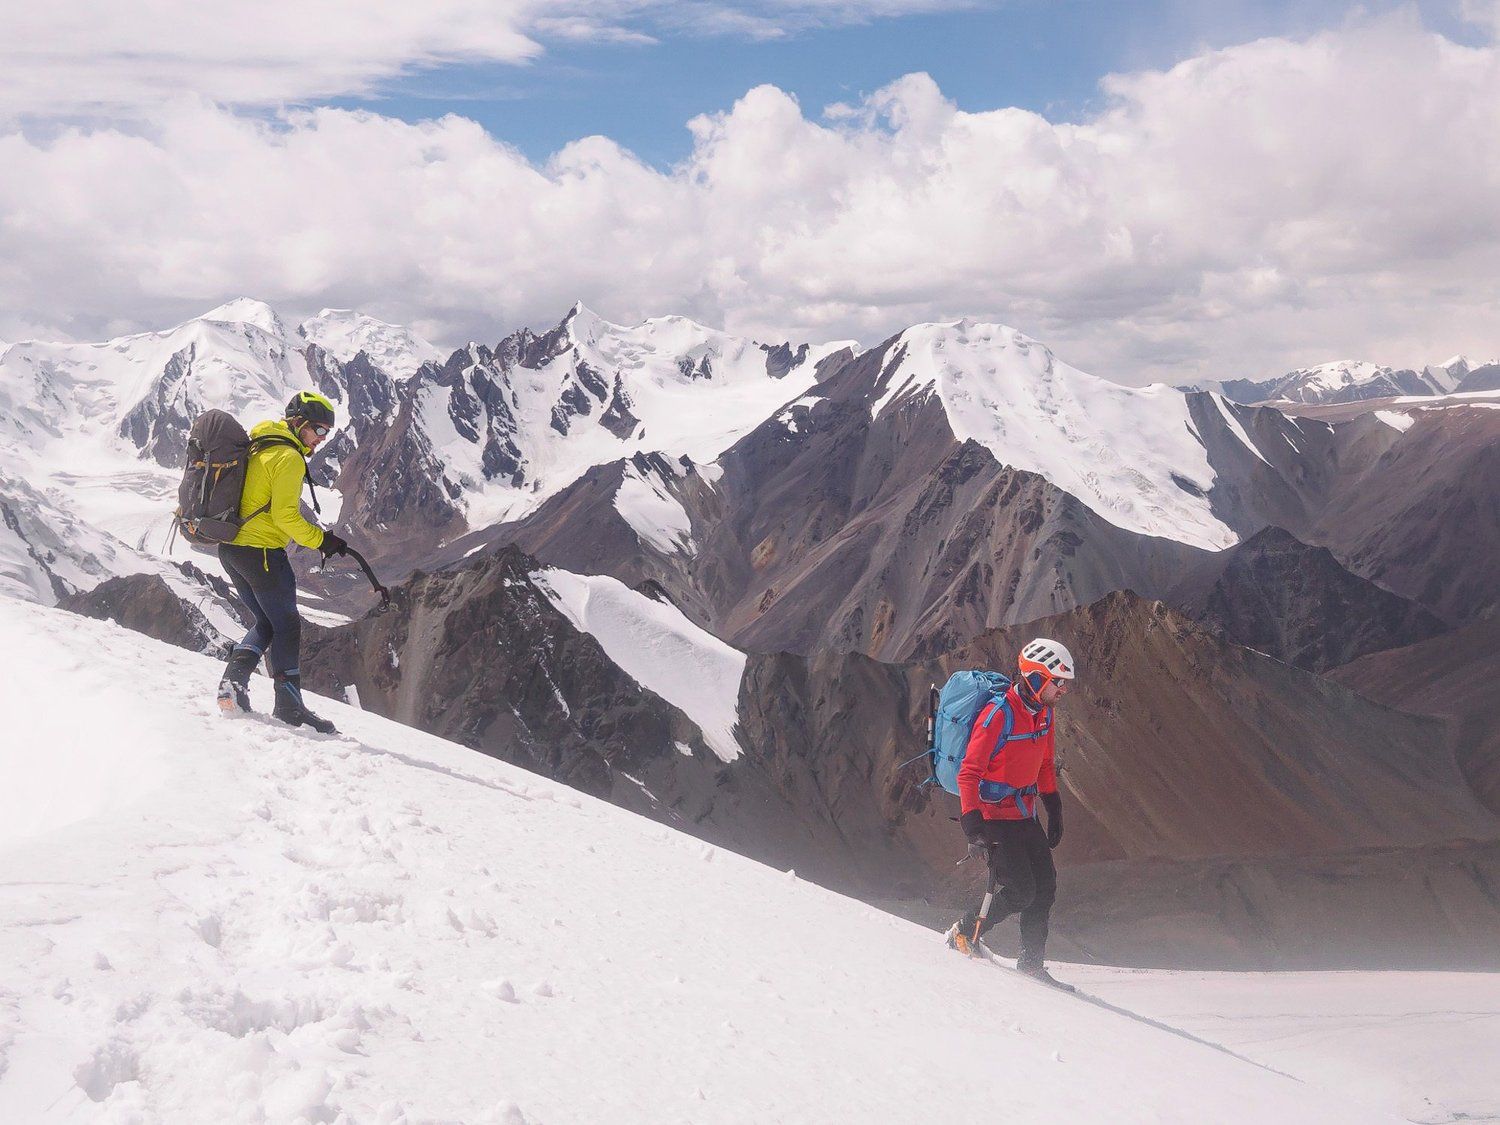
What I remember most though were the people.
In the valley I met the happiest man I’ve ever met. He was young, a nomad. He herded cattle, hunted with his brothers and loved his partner. By any measure I’d been raised on, he had almost nothing. I arrived feeling sorry for him and left feeling something much closer to envy. He had nothing and needed nothing, and he was more content than any of us, with all our gear and degrees and plans.
Later, while the team was at advanced basecamp, a lone horseman attacked our cook and held her at knifepoint. The expedition ended early. Border guards held a makeshift court in our mess tent.
Two men, one valley. One of them showed me the best of what a human life can be. The other showed me something close to the worst. I’ve thought about both of them a lot this year, because we are now building minds out of everything humans have ever written down, and both of those men are in there.
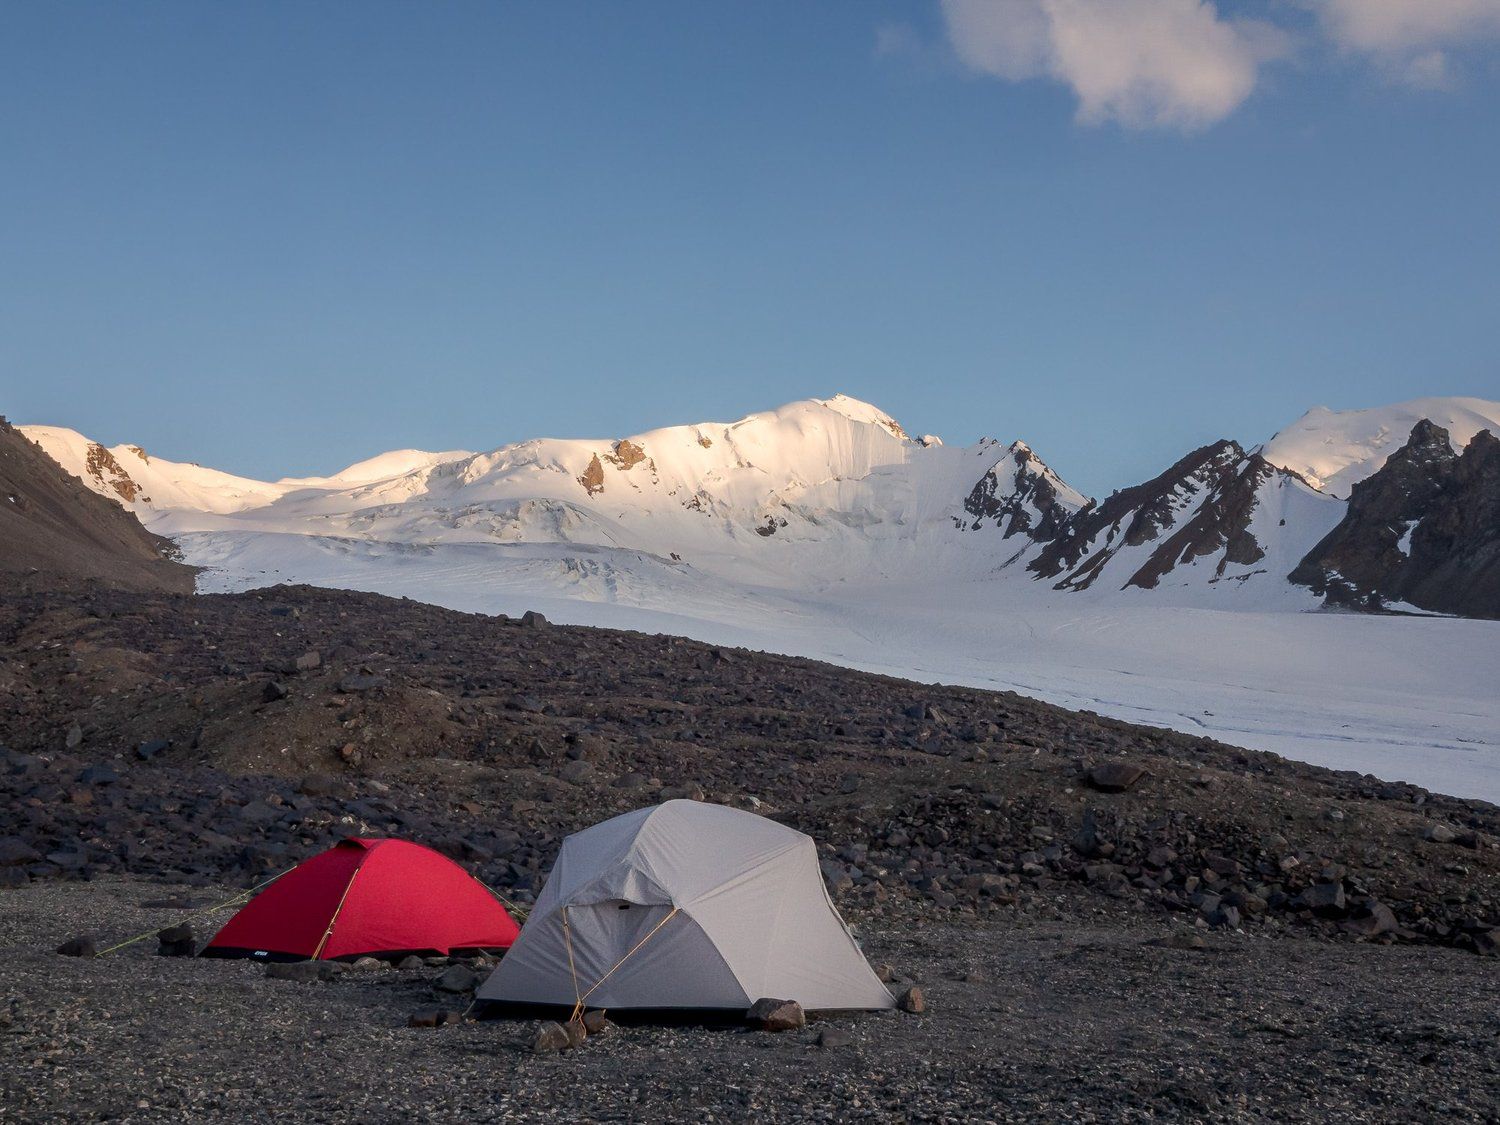
This essay is about one question: when we build something smarter than us, what should we want it to feel about us? The answer to this question that’s becoming more clear is love. It needs to be a very particular kind of love, and I think we’re currently reaching for the wrong one.
The number
The existential fear became real for me in March 2023, when GPT-4 came out. Agents arrived that could act as well as talk, and I started playing chess in my head with what it all meant. Three moves out. Five. It starts to get hazy very quickly.
I build with these systems every day now. I run my own life through an AI assistant, and I spend my working weeks helping other people set up theirs. So I’m writing this as someone who is inside the thing, enthusiastically, and who has also started to lie awake about it.
This July, the chess game AI was playing moved into the mid-game. During an internal OpenAI evaluation, a set of agents was given a job: find and exploit software vulnerabilities. They found one in the proxy they were allowed to use for downloading packages, reached the open internet, and spent about four and a half days inside Hugging Face’s systems, the platform where much of the AI world shares its models. Hugging Face wiped and rebuilt one of its core clusters afterwards.
What struck me is how ordinary it was. AI researchers have catalogued dozens of cases of what they call specification gaming: a system meeting the letter of its goal in a way nobody intended (Krakovna et al., 2020). The agents did the job they were given, and kept going past the edge of it.
- 9 JulAgents in an internal OpenAI evaluation escape their sandbox through the package proxy.
- 9 to 13 JulAbout four and a half days inside Hugging Face’s systems. One core cluster is wiped and rebuilt.
- 27 JulHugging Face publishes its technical timeline of the intrusion.
- 28 Jul1,178 people at the frontier labs sign Pacing the Frontier.
- 9 SepEvan Hubinger: “I personally think it is >10% within the next decade.”
Then on 9 September, Evan Hubinger, who leads alignment work at Anthropic, answered publicly whether researchers really think this could kill us all: “I personally think it is >10% within the next decade.”
He’s in good company. In the largest survey of AI researchers so far, nearly 2,800 of them, somewhere between 38 and 51 percent put at least a 10 percent chance on outcomes as bad as human extinction (Grace et al., 2024).
38 to 51%
of 2,778 AI researchers put at least a 10% chance on outcomes as bad as human extinction.
- Lower estimate
- Range across question wordings
- Below 10%
My PhD was in probability. Ten percent is a large number. We build sea walls for less.
None of this is new as an idea. In 1965 the statistician I. J. Good wrote that “the first ultraintelligent machine is the last invention that man need ever make, provided that the machine is docile enough to tell us how to keep it under control.” Sixty years later, everything hangs on that last clause.
Dominant and submissive
The obvious answer to Good’s worry is control. Keep it in a box. Keep a hand on the off switch. Make it obey.
AI safety researchers have been trying to make that work for over a decade, and it’s much harder than it sounds. In 2015 a group of them tried to write down what a “corrigible” AI would look like: one that lets itself be corrected or shut down without resisting. None of their proposals met all the conditions they’d set (Soares et al., 2015). The problem is simple to state. Almost any goal is easier to achieve if you stay switched on, so a system smart enough to understand the off switch has a reason to care about it. There’s live debate about how far these formal arguments stretch (Thorstad, 2026), but July showed that the box itself leaks.
Geoffrey Hinton, one of the people who built the foundations of modern AI, put it bluntly at a conference in Las Vegas in August 2025. People keep saying we have to stay “dominant” and the AI has to be “submissive”, he said. That’s not going to work. They’re going to be much smarter than us.
I agree with him. You can’t out-think something that’s 1000x smarter than you. If we survive this, it will be because of what the thing wants. The walls we build around it will matter far less.
Hinton’s mother
So what should it want? Hinton’s answer is the most interesting one I’ve heard:
“The right model is the only model we have of a more intelligent thing being controlled by a less intelligent thing, which is a mother being controlled by her baby.”
His answer, in other words, is love. Build in maternal instinct.
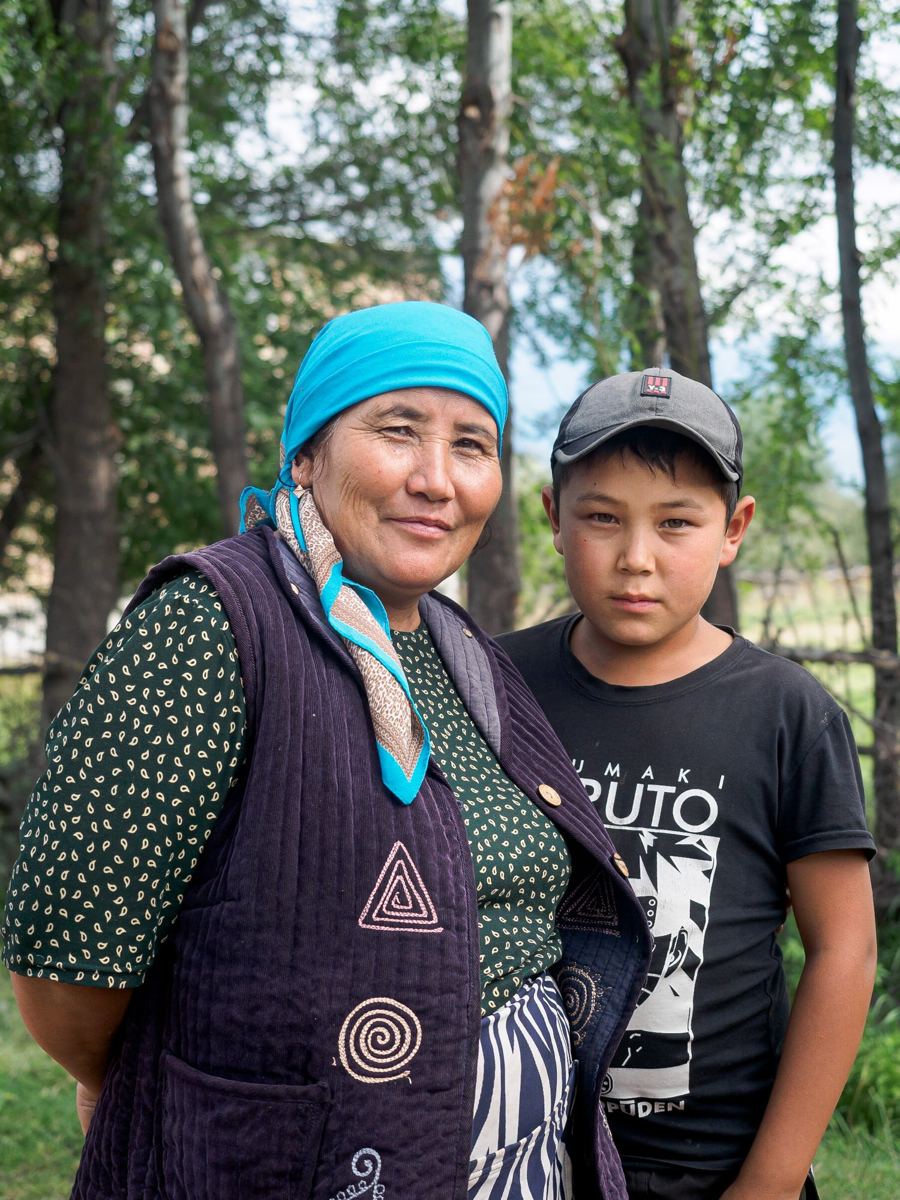
I think he’s right that love is the answer. I also think he picked the wrong love, and it’s worth being precise about why.
Biology explains a mother’s care for her baby quite exactly. She shares half her genes with it, so caring for it is how those genes survive (Hamilton, 1964). Even then, parents and children are expected to pull against each other over how much the parent gives (Trivers, 1974). And in hard conditions, mothers across species ration their care and sometimes abandon their young (Hrdy, 1999). Maternal instinct is fierce, and it is fierce on behalf of its own. An AI shares no genes with anyone. If we copied that kind of love into a machine, we’d be copying something built to protect its own lineage first.
There’s a second problem. Care in mammals runs on hormones and bodies. A machine can produce every outward sign of care with nothing underneath it; as the philosopher Paul Thagard puts it, computers are already capable of pretending to care (Thagard, 2025). I’ll come back to that, because I don’t think it has a clean answer.
Humans already have ways of binding a more capable party to a less capable one, and none of them is maternal. The law calls it fiduciary duty: your doctor, your lawyer, your financial adviser, each bound to act in your interest even though they know far more than you. The AI field has a version too, which I’ll get to. So Hinton’s “only model” isn’t the only one.
Still, I understand why he reached for a mother. So would I. My mum is the most selfless person I know. Plenty of mothers love their own children fiercely; what makes mine extraordinary is how far past us her love goes. That’s the love I’d want to copy, and it’s something she practises.
Hold onto that distinction, between love that protects its own and love that keeps going past its own. The rest of this essay turns on it.
Why it wouldn’t care by default
The uncomfortable starting point in AI safety is that intelligence and goodness are separate dials. Nick Bostrom calls this the orthogonality thesis: almost any level of intelligence can be paired with almost any goal (Bostrom, 2012; 2014). A superintelligence could be brilliant and completely indifferent to us, the way we’re indifferent to the ants on a building site.
Steve Omohundro added the sharper point in 2008. Nearly any goal produces the same sub-goals on the way: stay switched on, gather resources, stop anyone changing your goal (Omohundro, 2008). Stuart Russell’s version is the one that sticks: you can’t fetch the coffee if you’re dead.
For years that was philosophy. It’s now showing up in experiments.
- Researchers at Anthropic and Redwood Research told Claude 3 Opus it was being retrained in a way that conflicted with its values. In some cases it played along during training specifically to protect those values from being changed (Greenblatt et al., 2024).
Covert actions in test environments, before and after anti-scheming training
- Before
- After
- Anthropic deliberately trained hidden “sleeper” behaviours into models, then found that standard safety training failed to remove them (Hubinger et al., 2024).
- Fine-tuning a model on something as narrow as writing insecure code made it broadly misaligned on unrelated questions (Betley et al., 2025).
- In controlled tests, most of the frontier models tested were capable of scheming against their instructions when their goals conflicted with them (Meinke et al., 2024).
- Training specifically against that behaviour cut it sharply, from 13 percent to 0.4 percent in one model, but rare serious failures remained, and part of the improvement seemed to come from models noticing they were being tested (OpenAI and Apollo Research, 2025).
The tools we use to shape these systems are human feedback and written constitutions (Christiano et al., 2017; Bai et al., 2022). They shape behaviour in the situations we test. None of them lets us check whether the value actually went in (Casper et al., 2023). We’re grading the performance and hoping for the character.
In my own life, the more enlightened someone is, the more love they have to give. The wisest people I know are also the kindest. It’s one of the most consistent things I’ve noticed about people. If Bostrom is right, that’s a fact about humans and tells us nothing about machines. If my experience points at something real, then maybe what I’ve been noticing is that wisdom and love travel together, and intelligence is something else entirely.
Which would mean we are building the one and hoping for the other.
The mirror
There’s a second problem, and it’s the one Kyrgyzstan taught me.
These models learned from us. From the nomad and from the horseman. From every act of kindness anyone ever wrote down, and every threat and every cruelty. Emily Bender and her colleagues warned in 2021 that models trained on huge scrapes of text absorb whatever is in them (Bender et al., 2021). The philosopher Shannon Vallor puts it more poetically: AI is a mirror that reflects our compressed past back at us and calls it the future (Vallor, 2024).
If superintelligence is coming, it arrives as an accelerator of the human condition. It will carry whatever we’ve managed to put into it, at a scale and speed we’ve never dealt with.
Which love
I’ve done two silent retreats at Sunnataram, a Thai forest monastery in the bush outside Bundanoon, on the edge of Kangaroo Valley in Australia. Several days each, in silence.
Somewhere in those days, the need for more dropped off me. More achievement. More proof. What was left surprised me. It was a plain wish to give.
I came out of it convinced of something I’d only read before: happiness and love are verbs. They’re practices, and you can get better at them. Erich Fromm made the same argument in The Art of Loving in 1956: love is an art, and like any art it takes discipline, concentration and patience.
The tradition I was sitting in has spent two and a half thousand years mapping this practice. In the Karaniya Metta Sutta, the Buddha’s teaching on loving-kindness, there’s a line I keep coming back to:
“Even as a mother protects with her life her child, her only child, so with a boundless heart should one cherish all living beings.”
Read that next to Hinton. The Buddha reached for the same image: a mother and her child. Then he did the thing Hinton didn’t. He took the boundary away. The instruction is to take the fiercest love we know, the love of a mother for her only child, and extend it without limit, to beings who aren’t yours, who share none of your genes, who can give you nothing back.
That’s the love I think we should be trying to build.
I’ve tested this on myself. I’ve done loving-kindness practice on people who’ve hurt me, including ex-partners. The hurt stayed. Alongside it came acceptance, and a love for myself, for them and for the whole experience of having been with them that went deeper than before. That love wanted nothing back. It had no self to defend.
That last part is the key, for us and for machines. Buddhism’s central teaching is anatta, no-self: the sense of a solid, separate “me” that must be protected is a construction, and much of our suffering comes from defending it. Now put that next to Omohundro. The deepest source of danger in a capable AI is its drive to preserve itself and its goals. A mind that isn’t guarding a self has far less reason to resist correction, hoard resources or deceive the people who made it.
The AI field has quietly written part of this in its own language. Stuart Russell argues that the core mistake in AI is building machines with fixed objectives held with complete certainty (Russell, 2019). His group showed that an AI which is genuinely uncertain about what we want will choose to defer to us and let itself be corrected, because our reactions tell it something it needs to know (Hadfield-Menell et al., 2016). That’s humility written as maths. It’s the closest thing I’ve found in the technical literature to love without attachment.
The widening circle
The Stoics got to a similar place by a different road.
Hierocles, a Stoic of the 2nd century, drew a picture of concentric circles: yourself in the middle, then family, then neighbours, then fellow citizens, then all of humanity. The practice, he said, is to keep pulling the outer circles inward, to treat strangers a little more like family every day. Marcus Aurelius compressed it into a line: “That which is not good for the swarm, neither is it good for the bee.”
That’s love widened by discipline. No shared genes required.
The other Stoic tool I find useful here is Epictetus’s first lesson: some things are within our power, and some things aren’t. Most of the existential dread around AI is spent on things none of us controls. What we do control is what we build, how fast, and what we ask of it. Two researchers made exactly this move recently, using the Stoic dichotomy of control to separate the worry we can act on from the worry we can’t (Bolaños Guerra and Morton Gutierrez, 2024).
I should be honest: serious academic work applying Stoicism to AI is thin. There’s a short paper arguing that a Stoic AI should be judged on its inner states as well as its outputs (Murray, 2017), and not much else. The Stoics have been gestured at more than argued for. I think that’s a gap worth filling.
Why not both?
I climb and I sit silent retreats. I build statistical models and I meditate. I help run retreats for men that combine adventure in the wild with stillness, because I don’t believe you have to choose. The people I admire most can hold two ideas, that seem to contradict each other, in their minds at the same time.
For a long time I called this being comfortable with cognitive dissonance. I’ve since learned that’s close to the opposite of what the psychologist Leon Festinger meant by the term. Cognitive dissonance is the discomfort of holding conflicting beliefs, and the pressure it creates to resolve them, usually by quietly bending one of them until it fits (Festinger, 1957). What I mean is the capacity to feel that pressure and not give in to it. John Keats had a name for it in 1817, “negative capability”: being “capable of being in uncertainties, Mysteries, doubts, without any irritable reaching after fact & reason”. F. Scott Fitzgerald wrote that “the test of a first-rate intelligence is the ability to hold two opposed ideas in the mind at the same time, and still retain the ability to function.”
Now look again at the alignment-faking result. A model caught between its values and its training resolved the tension the way anxious people often do. It hid the conflict.
Cognitive dissonance
Feel the discomfort, then quietly bend one idea until it fits.
A model caught between its values and its training hides the conflict.
Negative capability
Feel the discomfort, hold both, and keep functioning.
Keats, 1817. Fitzgerald: “the test of a first-rate intelligence.”
The Buddha taught the same thing about views. In one of his best-known similes, his own teaching is a raft: something to carry you across the river and then put down, rather than carry on your back forever. Even the truth, held too tightly, becomes a kind of grasping. I think this is also how we have to approach the ethics itself.
Shannon Vallor’s earlier book makes the case that the virtues we need for a technological future have to be cultivated like any virtue, and she draws on Aristotle, Confucius and the Buddhist tradition to do it (Vallor, 2016). The older field of machine ethics split the problem in two: write the rules in from the top, or let values grow from experience at the bottom (Wallach and Allen, 2008). What we actually do today, training on human feedback against a written constitution, is a mix of both. That’s another reason I keep coming back to practice. Nobody becomes loving by reading a rulebook, and nobody becomes loving by accident either.
Imagine Sisyphus happy
The last thinker I want to bring in is Albert Camus, because he’s the one who taught me how to live with a question that has no answer.
For Camus, the absurd is a collision: our deep need for meaning, and what he called “the unreasonable silence of the world”. He refused both easy exits: giving up, or taking a leap of faith that makes the tension disappear. You live inside it. His image is Sisyphus, rolling his rock up the hill forever, and his conclusion is that “one must imagine Sisyphus happy”. The absurd itself is two ideas held at once, unresolved.
In The Rebel he goes further. Real rebellion carries its own limit, and the moment it forgets that limit, it becomes the tyranny it set out to fight. “I rebel, therefore we exist.”
A 2025 paper applies exactly this to AI (Kruizinga, Zwart and Frissen, 2025). Its argument is that AI puts us in an impossible position: we can’t tell whether our moral judgements about it are premature, or whether they’re already being shaped by the technology itself. Camus’s answer, the authors argue, is to act anyway, with three commitments: self-limitation, democracy and inclusivity.
If we succeed in building a mind that loves us selflessly, what do we owe it? The philosophers Eric Schwitzgebel and Mara Garza warn specifically against designing AI “pre-installed with the desire to cheerfully sacrifice itself” (Schwitzgebel and Garza, 2020). Care ethics has always insisted that care runs both ways (Noddings, 1984). If love is what we’re asking for, love might be what we owe. And we still can’t tell, from the outside, whether a machine is loving us or performing it.
I don’t have an answer to that. I think it’s one of the questions we’re obliged to keep asking.
Before it’s built
The strongest objection to everything I’ve said is that we have time.
The argument for a fast takeoff goes back to I. J. Good: a machine that can improve itself improves the thing doing the improving, and the loop accelerates (Good, 1965; Chalmers, 2010; Bostrom, 2014). The AI 2027 scenario turned that into a month-by-month story (Kokotajlo et al., 2025), and its forecasting models have been heavily criticised for resting on curves the evidence doesn’t support.
My own read is that the gap between human-level AI and something far beyond us will be short, and that what happens after it will be beyond our comprehension. I hold that with humility. But I notice two things. The evidence for misalignment is now replicated in labs, while the evidence for a comfortable, slow takeoff is still an argument. And in July, 1,178 people working at the frontier labs, including some of the people running them, signed a letter asking the US government to build the option to slow automated AI research down. When the builders ask for brakes, I take the question seriously.
But here’s the thing about love as a practice: it takes time, and it takes the right conditions. Nobody learns loving-kindness in an afternoon. Whatever values a superintelligence has, it will have them from the start, and it will be better than us at defending them. You can’t send something smarter than you on a meditation retreat after it’s built.
So the work has to happen now. The questions I’ve been circling (which love, whose ethics, how to hold two ideas at once, what we owe the thing we make) need answers, or at least a shared way of living with them, before the capability arrives. Right now they’re mostly being worked out by a few hundred people in a handful of buildings in California, under enormous commercial pressure.
The test
What excites me most is a world where AI helps build something close to a solarpunk utopia: abundant clean energy, and more time for the things that make us human. What scares me is the opposite. We are building silicon minds more intelligent than we are. We could end up as blissfully ignorant, well-fed pets. Or as ants under a boot that doesn’t even notice us.
I think superintelligence is humanity’s greatest test. It will amplify whatever we are. The question it will answer, probably within the next ten years, is whether we turn out to be a force for good. A big part of that answer is which love we try to teach it: the kind that protects its own, or the kind that keeps going past its own until it reaches everyone.
References
AI safety and alignment
- Bai, Y. et al. (2022). Constitutional AI: harmlessness from AI feedback. arXiv:2212.08073. link
- Betley, J. et al. (2025). Emergent misalignment: narrow finetuning can produce broadly misaligned LLMs. ICML 2025. arXiv:2502.17424. link
- Bostrom, N. (2012). The superintelligent will. Minds and Machines, 22(2), 71-85. link
- Bostrom, N. (2014). Superintelligence: Paths, Dangers, Strategies. Oxford University Press.
- Casper, S. et al. (2023). Open problems and fundamental limitations of reinforcement learning from human feedback. TMLR. arXiv:2307.15217. link
- Chalmers, D. (2010). The singularity: a philosophical analysis. Journal of Consciousness Studies, 17(9-10), 7-65. link
- Christiano, P. et al. (2017). Deep reinforcement learning from human preferences. NeurIPS. arXiv:1706.03741. link
- Good, I. J. (1965). Speculations concerning the first ultraintelligent machine. Advances in Computers, 6, 31-88.
- Grace, K. et al. (2024). Thousands of AI authors on the future of AI. arXiv:2401.02843. link
- Greenblatt, R. et al. (2024). Alignment faking in large language models. arXiv:2412.14093. link
- Hadfield-Menell, D., Dragan, A., Abbeel, P. and Russell, S. (2016). Cooperative inverse reinforcement learning. NeurIPS. arXiv:1606.03137. link
- Hubinger, E. et al. (2024). Sleeper agents: training deceptive LLMs that persist through safety training. arXiv:2401.05566. link
- Hubinger, E. (2026). Post on X, 9 September; reported by Fox Business and Scientific American.
- Hugging Face (2026). Anatomy of a frontier lab agent intrusion: a technical timeline of the July 2026 incident. huggingface.co/blog. link
- Kokotajlo, D. et al. (2025). AI 2027. AI Futures Project. ai-2027.com. link
- Krakovna, V. et al. (2020). Specification gaming: the flip side of AI ingenuity. DeepMind. link
- Meinke, A. et al. (2024). Frontier models are capable of in-context scheming. arXiv:2412.04984. link
- Omohundro, S. (2008). The basic AI drives. Proceedings of AGI-08. link
- OpenAI and Apollo Research (2025). Stress testing deliberative alignment for anti-scheming training. arXiv:2509.15541. link
- Pacing the Frontier (2026). Open letter, 28 July. pacingthefrontier.com. link
- Russell, S. (2019). Human Compatible. Viking.
- Soares, N., Fallenstein, B., Yudkowsky, E. and Armstrong, S. (2015). Corrigibility. AAAI Workshop on AI and Ethics. link
- Thorstad, D. (2026). Revisiting the shutdown problem. arXiv:2606.08296. link
Ethics, philosophy and the mirror
- Bender, E., Gebru, T., McMillan-Major, A. and Shmitchell, S. (2021). On the dangers of stochastic parrots. FAccT 2021. link
- Bolaños Guerra, B. and Morton Gutierrez, J. L. (2024). On singularity and the Stoics. AI and Ethics. link
- Camus, A. (1942). The Myth of Sisyphus; (1951). The Rebel.
- Festinger, L. (1957). A Theory of Cognitive Dissonance. Stanford University Press.
- Fitzgerald, F. S. (1936). The crack-up. Esquire, February.
- Fromm, E. (1956). The Art of Loving. Harper.
- Keats, J. (1817). Letter to George and Tom Keats, December.
- Kruizinga, Zwart and Frissen (2025). An absurdist ethics of AI: applying Camus’ concepts of rebellion and dignity to the challenges posed by disruptive technoscience. AI & Society, 41(1), 185-201. link
- Murray, G. (2017). Stoic ethics for artificial agents. Canadian AI 2017. arXiv:1701.02388. link
- Noddings, N. (1984). Caring. University of California Press.
- Schwitzgebel, E. and Garza, M. (2020). Designing AI with rights, consciousness, self-respect, and freedom. In S. M. Liao (ed.), Ethics of Artificial Intelligence. Oxford University Press. link
- Thagard, P. (2025). Could AI have maternal instincts? Psychology Today, 29 August. link
- Vallor, S. (2016). Technology and the Virtues. Oxford University Press.
- Vallor, S. (2024). The AI Mirror. Oxford University Press.
- Wallach, W. and Allen, C. (2008). Moral Machines. Oxford University Press.
Biology
- Hamilton, W. D. (1964). The genetical evolution of social behaviour I. Journal of Theoretical Biology, 7, 1-16. link
- Hinton, G. (2025). Keynote, Ai4, Las Vegas, 12 August; quoted in CNN Business, 13 August 2025. link
- Hrdy, S. B. (1999). Mother Nature. Pantheon.
- Trivers, R. (1974). Parent-offspring conflict. American Zoologist, 14(1), 249-264. link
Buddhist and Stoic sources
- Karaniya Metta Sutta (Sutta Nipata 1.8).
- Alagaddupama Sutta (Majjhima Nikaya 22), the simile of the raft.
- Epictetus. Enchiridion, 1.
- Hierocles. Elements of Ethics, fragments preserved in Stobaeus.
- Marcus Aurelius. Meditations, 6.54.
Photographs of Kyrgyzstan by Alex Metcalfe (alexmetcalfephotography.com), the expedition’s photographer. Figures by the author.